معرفی Prime Mega MoE؛ هسته ادغامشده جدید برای سرعتبخشی به آموزش مدلهای هوش مصنوعی
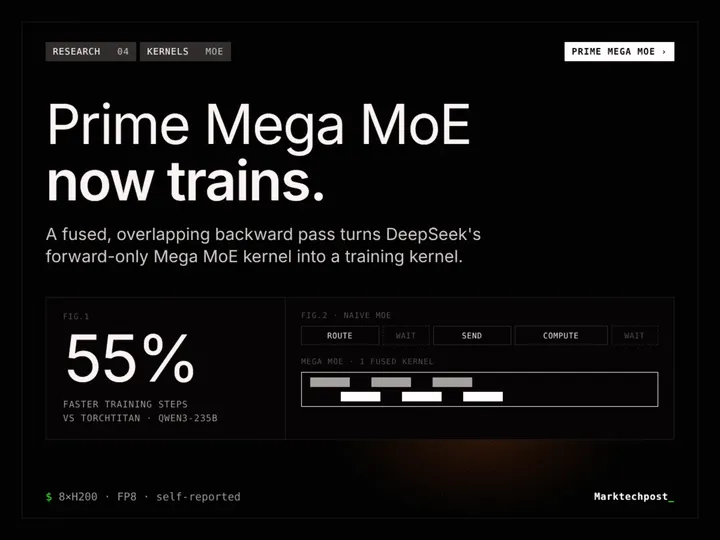
شرکت Prime Intellect از افزونه آموزشی Prime Mega MoE رونمایی کرد که با افزودن بخش بازگشت سریع به هسته دیپسیک، امکان استفاده از آن را در مرحله آموزش مدلهای ترکیبی کارشناسان فراهم میکند. این هسته جدید سرعت مراحل آموزش کامل را تا بیش از ۵۰ درصد نسبت به ابزارهای رایج افزایش میدهد.
شرکت Prime Intellect از انتشار Prime Mega MoE رونمایی کرد که در واقع یک افزونه آموزشی برای هسته ادغامشده Mega MoE شرکت دیپسیک محسوب میشود. هسته اصلی دیپسیک تنها از گذرگاه جلو پشتیبانی میکرد، اما پژوهشگران Prime Intellect با افزودن یک گذرگاه بازگشت سریع و همپوشان، این هسته را برای استفاده در فرآیند آموزش مدلهای هوش مصنوعی نیز کاربردی کردهاند. این نوآوری موجب کاهش چشمگیر ساعات پردازشی مورد نیاز روی کارتهای گرافیکی میشود.
آزمایشهای انجامشده نشان میدهد که مراحل آموزش کامل مدلهای هوش مصنوعی مجهز به ساختار MoE با استفاده از این هسته جدید، بین ۳۲ تا ۳۴ درصد سریعتر از خط لوله پایه و تا ۵۵ درصد سریعتر از پلتفرم TorchTitan اجرا میشوند. بیشترین میزان بهبود در بخش گذرگاه جلو مشاهده شده که سرعت آن تا ۳.۱۱ برابر افزایش یافته است، در حالی که بهبود گذرگاه بازگشت در مدلهای بزرگتر کمتر بوده است.
این هسته جدید از انواع دادههای مختلف از جمله BF16 و فرمتهای FP8 پشتیبانی میکند و برای اجرا روی پردازندههای گرافیکی انویدیا از جمله معماریهای هوپر و بلکول بهینهسازی شده است. توسعهدهندگان میتوانند از طریق مخزن رسمی و ابزارهای مرتبط به این هسته دسترسی داشته باشند و آن را در فرآیندهای یادگیری ماشین خود به کار بگیرند.
Prime Intellect Releases Prime Mega MoE: Trainable Fused MoE Kernel, 3.11x Faster Forward Pass
Prime Intellect has released Prime Mega MoE , a training extension of DeepSeek’s fused Mega MoE kernel. DeepSeek’s kernel only ran the forward pass. Prime Intellect added a fast, overlapping backward pass. That makes the fused kernel usable for training, not just inference. In its prime-rl trainer, full training steps on Qwen3 MoE models run up to 34% faster. Against TorchTitan, the gain reaches 55%. For teams…
Prime Intellect has released Prime Mega MoE , a training extension of DeepSeek’s fused Mega MoE kernel. DeepSeek’s kernel only ran the forward pass. Prime Intellect added a fast, overlapping backward pass. That makes the fused kernel usable for training, not just inference. In its prime-rl trainer, full training steps on Qwen3 MoE models run up to 34% faster. Against TorchTitan, the gain reaches 55%. For teams training mixture-of-experts (MoE) models, that is a direct cut in GPU hours. TL;DR Size: A GPU kernel, not a model. Tested on Qwen3-30B-A3B and Qwen3-235B-A22B (128 experts, top-8 routing). Runs on: NVIDIA Hopper (blockwise FP8) and Blackwell (MXFP8) GPUs, BF16 on both. Published numbers use 8×H200 nodes, 32 to 128 GPUs. Performance: 32% to 34% faster full training steps than the prime-rl baseline. 48% to 55% faster than TorchTitan. Best: 3.11x faster forward pass on a Qwen3-30B-A3B MoE layer (12.0 ms to 3.9 ms). Worst: 1.24x backward pass on a Qwen3-235B-A22B MoE layer (30.5 ms to 24.6 ms). What is Prime Mega MoE? Prime Mega MoE is a fused, overlapping MoE kernel for training from Prime Intellect. It builds on the Mega MoE kernel in DeepSeek’s open-source DeepGEMM library. Why is MoE training communication-bound? In an MoE model, each token goes to a small subset of experts. Those experts sit on different GPUs. So every layer sends tokens out, runs expert math, and sends results back. This happens in the forward pass and again in the backward pass. In a standard setup, these are separate operations. The GPU sorts tokens and waits on the transport layer. Then it computes, hands results back, and waits again. Those waits are idle GPU time. How does the fused kernel work? DeepSeek’s Mega MoE , added to DeepGEMM in April 2026, replaces that chain with one kernel call. It fuses expert-parallel dispatch, the 2 expert linear layers, SwiGLU, and combine. While one token group is in transit, the kernel computes on a group that already arrived. It also skips intermediate tensors by using GPU-only scratch buffers. But it only shipped a forward implementation. Prime Intellect wrote the missing backward kernel, also overlapping. Supported types are BF16, MXFP8 (Blackwell only) and blockwise FP8 (Hopper only). The prime-rl config also exposes an fp8_bwd mode: BF16 forward, FP8 backward. &&&& How fast is Prime Mega MoE? All numbers below are self-reported by Prime Intellect. Training steps use 8×H200 nodes, FP8, 16,384-token sequences and full activation checkpointing. Each result is the mean of steps 6 to 20. Full training step, seconds (lower is better): Model (cluster) prime-rl baseline TorchTitan (FP8) Prime Mega MoE Gain vs baseline Gain vs TorchTitan Qwen3-30B-A3B (32 H200) 2.78 3.07 2.08 34% 48% Qwen3-235B-A22B (128 H200) 12.72 14.98 9.65 32% 55% Against TorchTitan, throughput rose from 5,337 to 7,886 tokens/s/GPU on the 30B model. On the 235B model, it rose from 1,094 to 1,697. The prime-rl baseline uses torch all-to-all plus DeepGEMM FP8 experts. Single MoE layer, milliseconds (1 node, 8×H200, EP=8, 128 experts, top-8, random routing): Layer Forward Backward Full layer (2x fwd + bwd) Qwen3-30B-A3B 12.0 to 3.9 (3.11x) 15.4 to 8.2 (1.87x) 39.3 to 15.9 (2.47x) Qwen3-235B-A22B 20.7 to 9.5 (2.17x) 30.5 to 24.6 (1.24x) 71.9 to 43.7 (1.64x) The pattern is clear. Forward gains are large, and backward gains are smaller. The headline “up to 3.11x” refers to the forward pass only. How does it compare with other fused MoE options? Feature Prime Mega MoE DeepGEMM Mega MoE TorchTitan + DeepEP AMD Primus MegaMoE Developer Prime Intellect DeepSeek PyTorch, Nebius AMD Training (backward) Yes, fused and overlapping No, forward only Yes (separate dispatch kernels) Yes, per design docs Compute and comms fused Yes Yes No Yes (dispatch+GEMM1, GEMM2+combine) GPUs Hopper, Blackwell SM90, SM100 (library) B200 in published runs MI355X (gfx950) Data types BF16, MXFP8, blockwise FP8 FP8xFP8, FP8xFP4 BF16, MXFP8 grouped GEMMs BF16, MXFP8 Published speedup Up to 55% step time vs TorchTitan Not disclosed Up to 41% on DeepSeek-V3 671B Not disclosed License Apache 2.0 ( prime-rl ) MIT BSD-3-Clause MIT TorchTitan’s 41% gain comes from a different setup (B200, 671B model, BF16 baseline). It is not directly comparable. How do developers use it? Prime Mega MoE is a dispatch backend in prime-rl. Set type = "mega_moe" under [trainer.model.moe.dispatch] . Choose precision from bf16 , mxfp8 , fp8 or fp8_bwd . The training kernels ship in a prebuilt DeepGEMM wheel from prime-kernels . The stock DeepGEMM build lacks them. Key Takeaways Prime Mega MoE adds a fused, overlapping backward pass to DeepSeek’s Mega MoE. Full training steps run 32% to 34% faster than the prime-rl baseline. Against TorchTitan, steps run 48% to 55% faster on Qwen3 MoE models. Forward gains reach 3.11x, but backward gains drop to 1.24x on large layers. It ships in prime-rl as the mega_moe dispatch backend. Check out the Prime Mega MoE blog post , the announcement on X , and the prime-rl repo . Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter . Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Source report: MarkTechPost.
گزارش فارسی این خبر با کمک هوش مصنوعی و فقط بر اساس اطلاعات منتشرشده در منبع تهیه شده است.